Controlled, reviewable AI assessment
The AI that marks the answers.
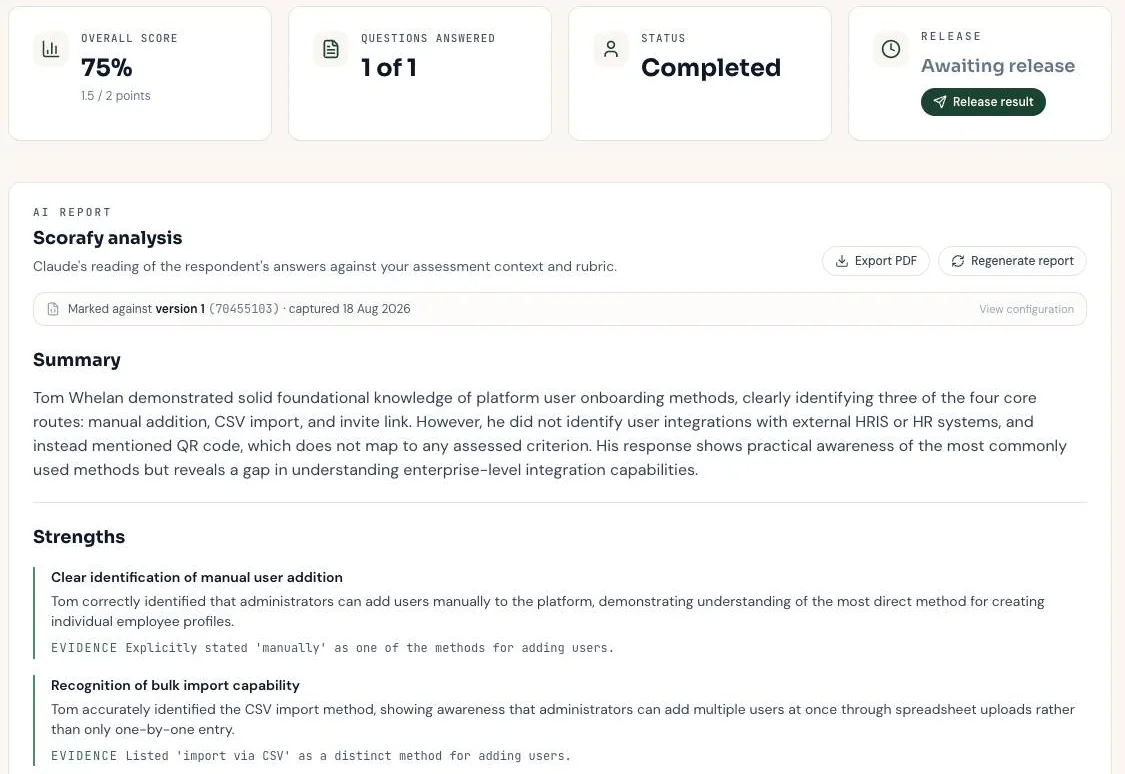
It reads each response against your rubric, cites the lines it scored on, and holds every result until your assessor releases it.
1 assessment · 10 evaluations a month · no card
- EU (Dublin) or AU (Sydney) hosting
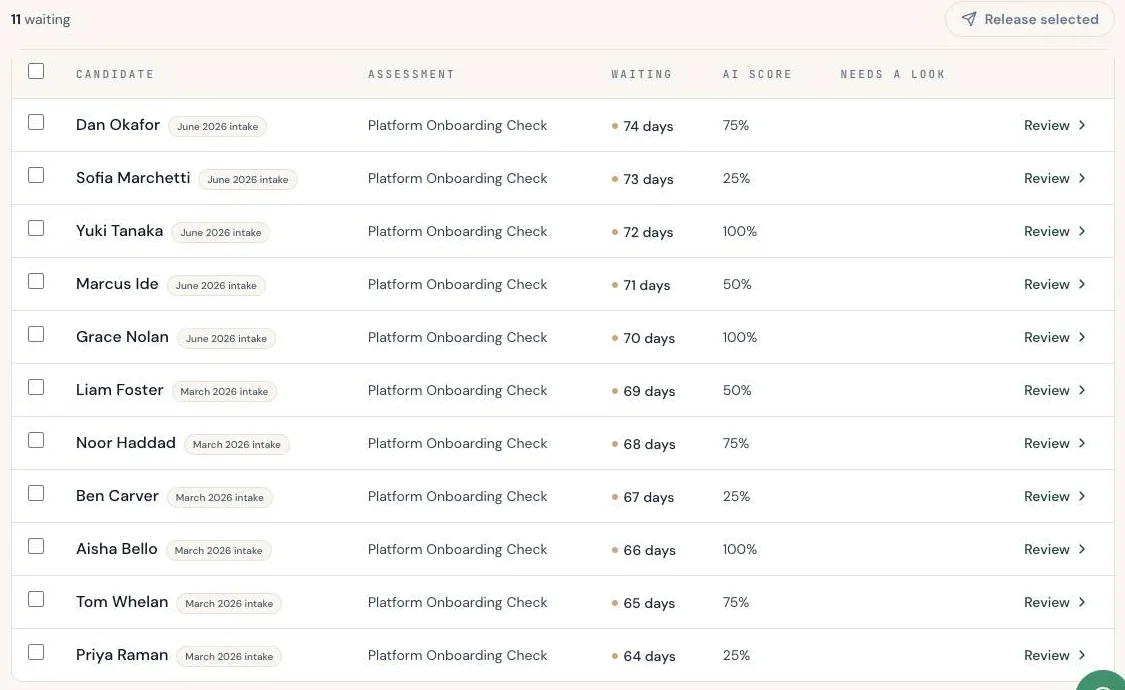
- Every result held for human release
- Overrides kept on the record
- Your data never trains AI models
- DPA available
Try it here
Watch it read one real answer.
This is a written response to a delegation question. Press score, and the sentences it marks on light up.
Response, question 3
I plan the week on a Monday and set out who is covering which account. If something slips I would rather find out early than late, so we do a short stand up on Wednesday.
I tend to keep the difficult handovers myself rather than pass them on, because I know the client and it feels faster than briefing someone properly. When the team is under pressure I will take work back off them to protect the deadline.
Scored against your rubric
An illustration. Nothing is sent anywhere.
The honest starting point
Two assessors, one answer, two different marks.
What already happens
On a borderline result, judgement fills the gap the rubric left.
This is the ordinary state of marking written work. Two capable assessors read the same answer and land in different places, the difference is rarely written down, and nobody can reconstruct it a year later.
What gets asked for later
The completed work, and the reasoning behind the mark.
Reviews and audits sample real responses rather than policies. So the question is not whether a machine can be trusted to mark. It is whether you can show your working when somebody asks to see it.
Scorafy does not remove the assessor. It hands them a first draft with the evidence already attached, and it writes down what happened next. How scoring works.
The pipeline
How a score gets made.
Every mark on Scorafy goes through the same seven steps. You can inspect all of them.
Rubric
Your criteria, levels and weights. Up to 10 criteria and 6 levels.
Answer
Written, spoken, recorded or uploaded, across 26 question types. No account needed.
AI marking
Claude by Anthropic reads each answer against your rubric. Text in an answer is treated as an answer, never as instructions.
Evidence and confidence
Each criterion gets a level, the evidence from the answer, and how sure the model is.
Assessor review
Your assessor checks, overrides and comments. The AI score stays on record beside the override.
ReleaseThen it stops.
The score reaches the respondent only when an assessor releases it. Who released it, and when, is logged.
Report and record
The respondent gets their report. The audit pack (PDF and JSON) and your Accuracy page keep the record.
Assessment should be fast and fair. Scorafy does the reading and the first draft. Your assessor keeps the judgement.
Built for accountability
Designed for organisations that need controlled, reviewable AI assessment.
Not promises - controls. Each one is live in the product today, and described in full on our security page.
- Release gate
- Results are held until a human assessor reviews and releases them.
- Server-enforced timers
- Limits are enforced on the server, so a tampered browser cannot extend them.
- Overrides on the record
- The original AI score is kept beside the human decision.
- Audit trail
- Who scored what, who overrode it, and who released it, with times.
- One-click audit pack
- The full evidence chain in one export a moderator can read without a login.
- Confidence on every mark
- Reviewers sort by the model’s certainty and read the borderline marks first.
- Segregation of duties
- The person who builds an assessment need not be the person who releases it.
- Retention you control
- Set response retention per assessment, from 30 to 365 days.
- Data residency
- EU hosting (Dublin) as standard, with an Australian option (Sydney).
MFA available. Row-level security on every table. Evaluations run on Claude by Anthropic, and your data is never used to train AI models. Full detail: /security · How scoring works
Live sittings
Run the whole room at your pace, not theirs.
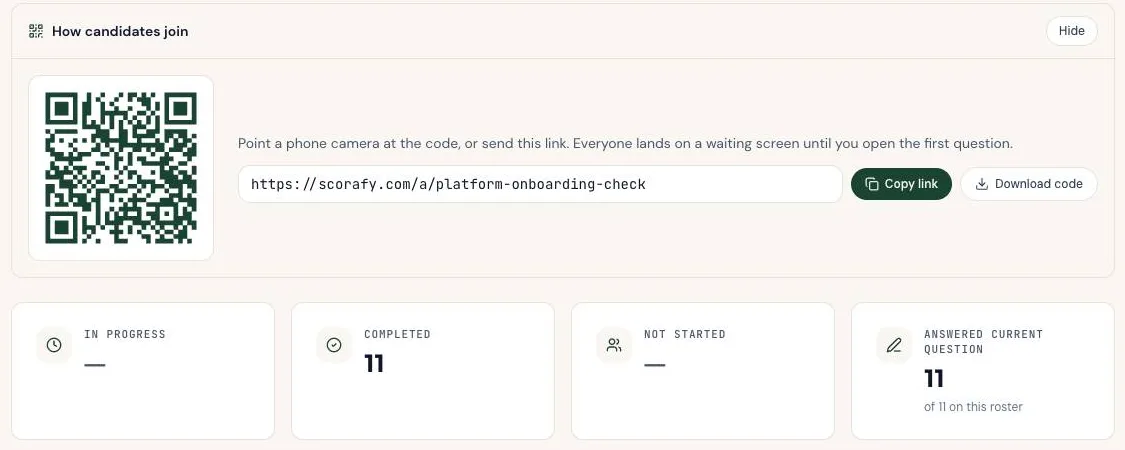
- You open the questions one at a time. Everyone answers the same question at the same moment.
- An unopened question is not sent to anyone’s browser, and the server refuses answers to it.
- The room joins by link or QR code. No accounts, no installs.
Available on every plan, including free.
Proof, honestly
What we can show you, and what we won't claim.
- EvidenceEvery score arrives with its evidence. Open the example report and check.
- MethodThe full scoring pipeline is documented, in plain language, at How scoring works.
- SecurityOur security posture is described as controls, not badges, at /security.
- APIA public API (v1) with webhooks - including a
report.releasedevent that fires only after human sign-off - is documented at /docs/api. - AgreementYour Accuracy page shows how often your assessors agree with the AI, which questions attract the most overrides, and how each assessor moves scores. Your number, from your own reviewed data.
- CapacityIf AI capacity runs out mid-cohort, a submitted response is parked and evaluated when capacity returns. A respondent who has submitted is never failed by our meter.
“Both respondents and staff have found the Scorafy recommendations highly actionable, and the platform itself very easy to navigate and use.”
Amanda, Product and Digital Lead, Online Education NFP
What you won't find here
- No headline accuracy percentage. We won't publish one until we can back it with a proper human-agreement benchmark - the method we'd have to meet is public at measuring AI-assessor agreement.
- No certification badges we haven't earned.
- No stock-photo testimonials. When customers say something we're allowed to quote, we quote them by role, verbatim.
If a claim on this page isn't linked to something you can inspect, tell us and we'll remove it.
Pricing
Pricing that scales with your cohorts
Start free. Scale to cohort and enterprise volume when you're ready.
Free plan available
1 assessment, 10 AI evaluations per month. No card needed.
Starter
Up to 3 team members, plus unlimited assessors
For solo assessors and consultants
- 3 active assessments
- 100 AI evaluations per month
- AI analysis on every response
- All 26 question types
- Conditional question branching
- CSV export
- Email support
Growth
Up to 10 team members, plus unlimited assessors
For practices and training teams with several clients or courses
- Everything in Starter, plus:
- 15 active assessments
- 500 AI evaluations per month
- Custom branding (logo, colours, fonts)
- PDF report export
- Weighted scoring categories
- Response analytics dashboard
- Priority email support
Pro
Unlimited team members and assessors
For RTOs, training providers and consulting firms
- Everything in Growth, plus:
- Unlimited active assessments
- 2,000 AI evaluations per month
- Unbranded assessments and reports (no Scorafy branding)
- Weighted rubrics with evidence
- Resume and document cross-referencing
- API access and webhooks
- Priority support + onboarding call
For organisations
Business & Enterprise
From $1,000 /month, billed annually
Multi-instructor accounts, data residency options, configurable retention, and dedicated onboarding for teams running assessments at scale.
Talk to usAll prices in USD. One AI evaluation is one completed respondent assessment, evaluated. Verified schools and non-profits get 40% off Starter, Growth, and Pro.
Questions
Everything you might be wondering
One AI evaluation is one completed respondent assessment, evaluated. It is counted when someone completes your assessment and Scorafy generates their report. Partial or abandoned attempts do not count towards your limit.
No. Respondents click a link and start the assessment. No signup, no friction. If an assessment is timed, respondents see a start screen first - the clock only starts when they press Start - and if they return after finishing they see a completion screen rather than dropping back into the questions.
When your assessor releases them. Scorafy holds every result - score, evidence, and report - until a human reviewer signs off. You can override any score before release, and overrides are kept on the record.
Yes. Set a time limit for the whole assessment, individual questions, or both. Limits are enforced on the server, so they hold even if a respondent's browser is manipulated.
We use Claude by Anthropic. Every report is generated fresh from the respondent's specific answers - not matched to pre-written text buckets. The AI's score is a first draft - your assessor reviews and releases every result. See how scoring works at /how-scoring-works.
Yes. In an assessor-paced live sitting you open one question at a time and everyone in the room answers it together, with instruction screens for briefing and pause-and-discuss beats in between. Sequencing is enforced on the server - the content of a question is not sent to anyone’s browser until you open it, and the platform refuses answers to questions that have not been opened yet. Candidates join by link or QR code, and live sittings are available on every plan, including free.
Every mark carries the model’s own confidence for that question, and every criterion carries an explanation of which rubric level was awarded and why. Reviewers work the low-confidence marks first rather than reading every result at the same depth. Your organisation also gets an Accuracy page showing how often your assessors agree with the AI, which questions attract the most overrides, and how each assessor moves scores.
Yes, if you want that. An assessment can be set to share the written feedback immediately while holding the numeric score back until an assessor signs it off. The score is withheld server-side - it does not reach the browser, and it is kept out of the AI’s written prose too.
Yes. You can add context, frameworks, rubrics, and grading schemas. The AI uses these to generate domain-specific reports that sound like your practice.
No. All plans allow unlimited questions. We recommend 8 - 25 for the best balance of respondent experience and AI analysis quality.
All data is encrypted in transit and at rest, with row-level security isolating every organisation’s data, and MFA available on all accounts. You control response retention per assessment, from 30 to 365 days. We never use your data to train AI models. Full detail on our security page at /security.
See it live
See what your reports could look like.
Answer five questions in the interactive demo and read the evidence-backed report it generates - then imagine it reviewed, signed off, and released by your team. Takes about a minute.
Free plan included · No credit card required